CoaG: Cylinders on a Grid
Coarse 3D layout control for video generation
Zhangsihao Yang (zshyang1106@gmail.com) · Mengyi Shan (University of Washington, shanmy@cs.washington.edu) · research preview, September 2026
Paper (draft PDF, Google Drive)Code + editorLoRA weightsData (Google Drive)
A user draws the crudest possible 3D scene, a ground grid and one cylinder per person, and moves the cylinders and the camera over 81 frames. A LoRA on Wan2.2-Fun-Control turns that sketch into a photoreal video in which the people stand where the cylinders stand, move as the cylinders move, and the camera moves as the drawn camera moves. Appearance comes from the text and a background reference image; layout and motion come from the geometry. The training pairs come from an automatic engine that lifts text-to-video output back to its geometry, with no real footage and no manual labels.
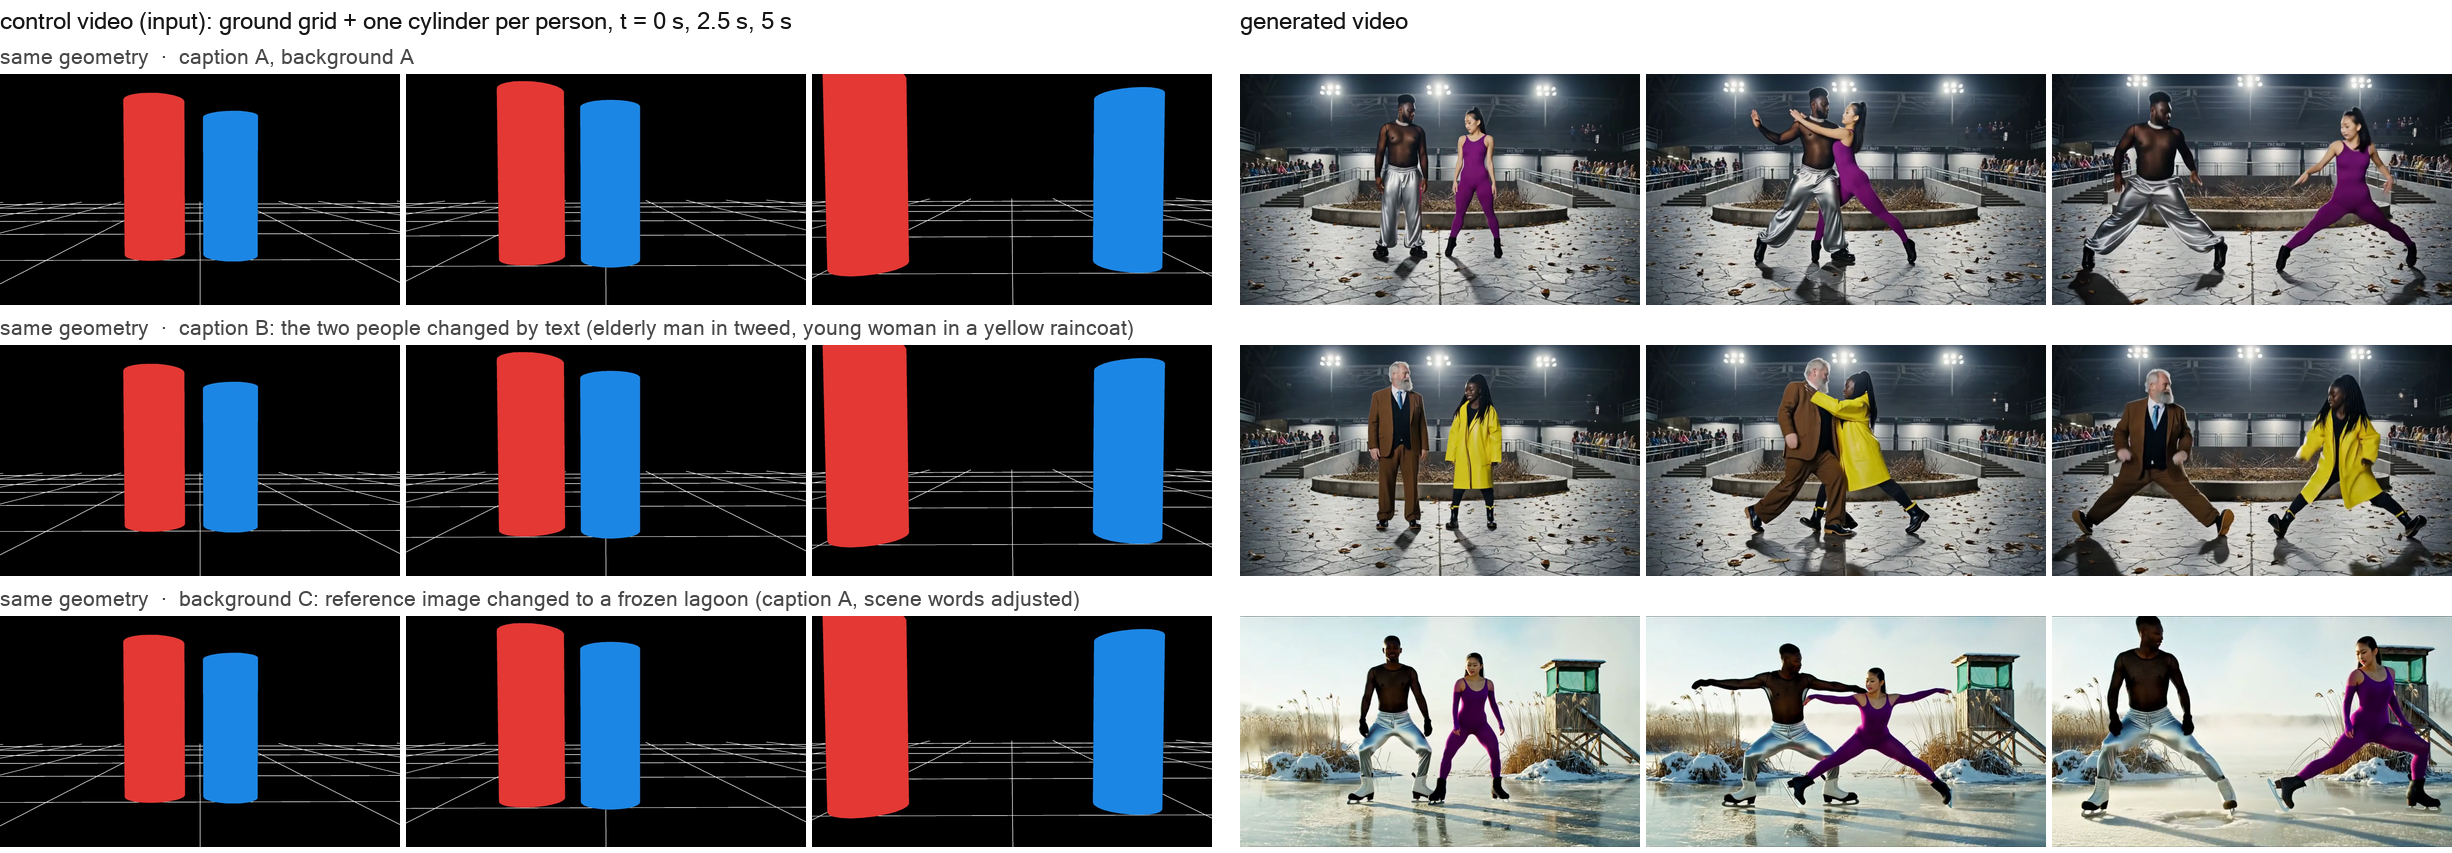
Left: the control video (three of 81 frames). Right: generated videos. The rows share the geometry and differ only in the text (row 2) or the background reference image (row 3).
Overview
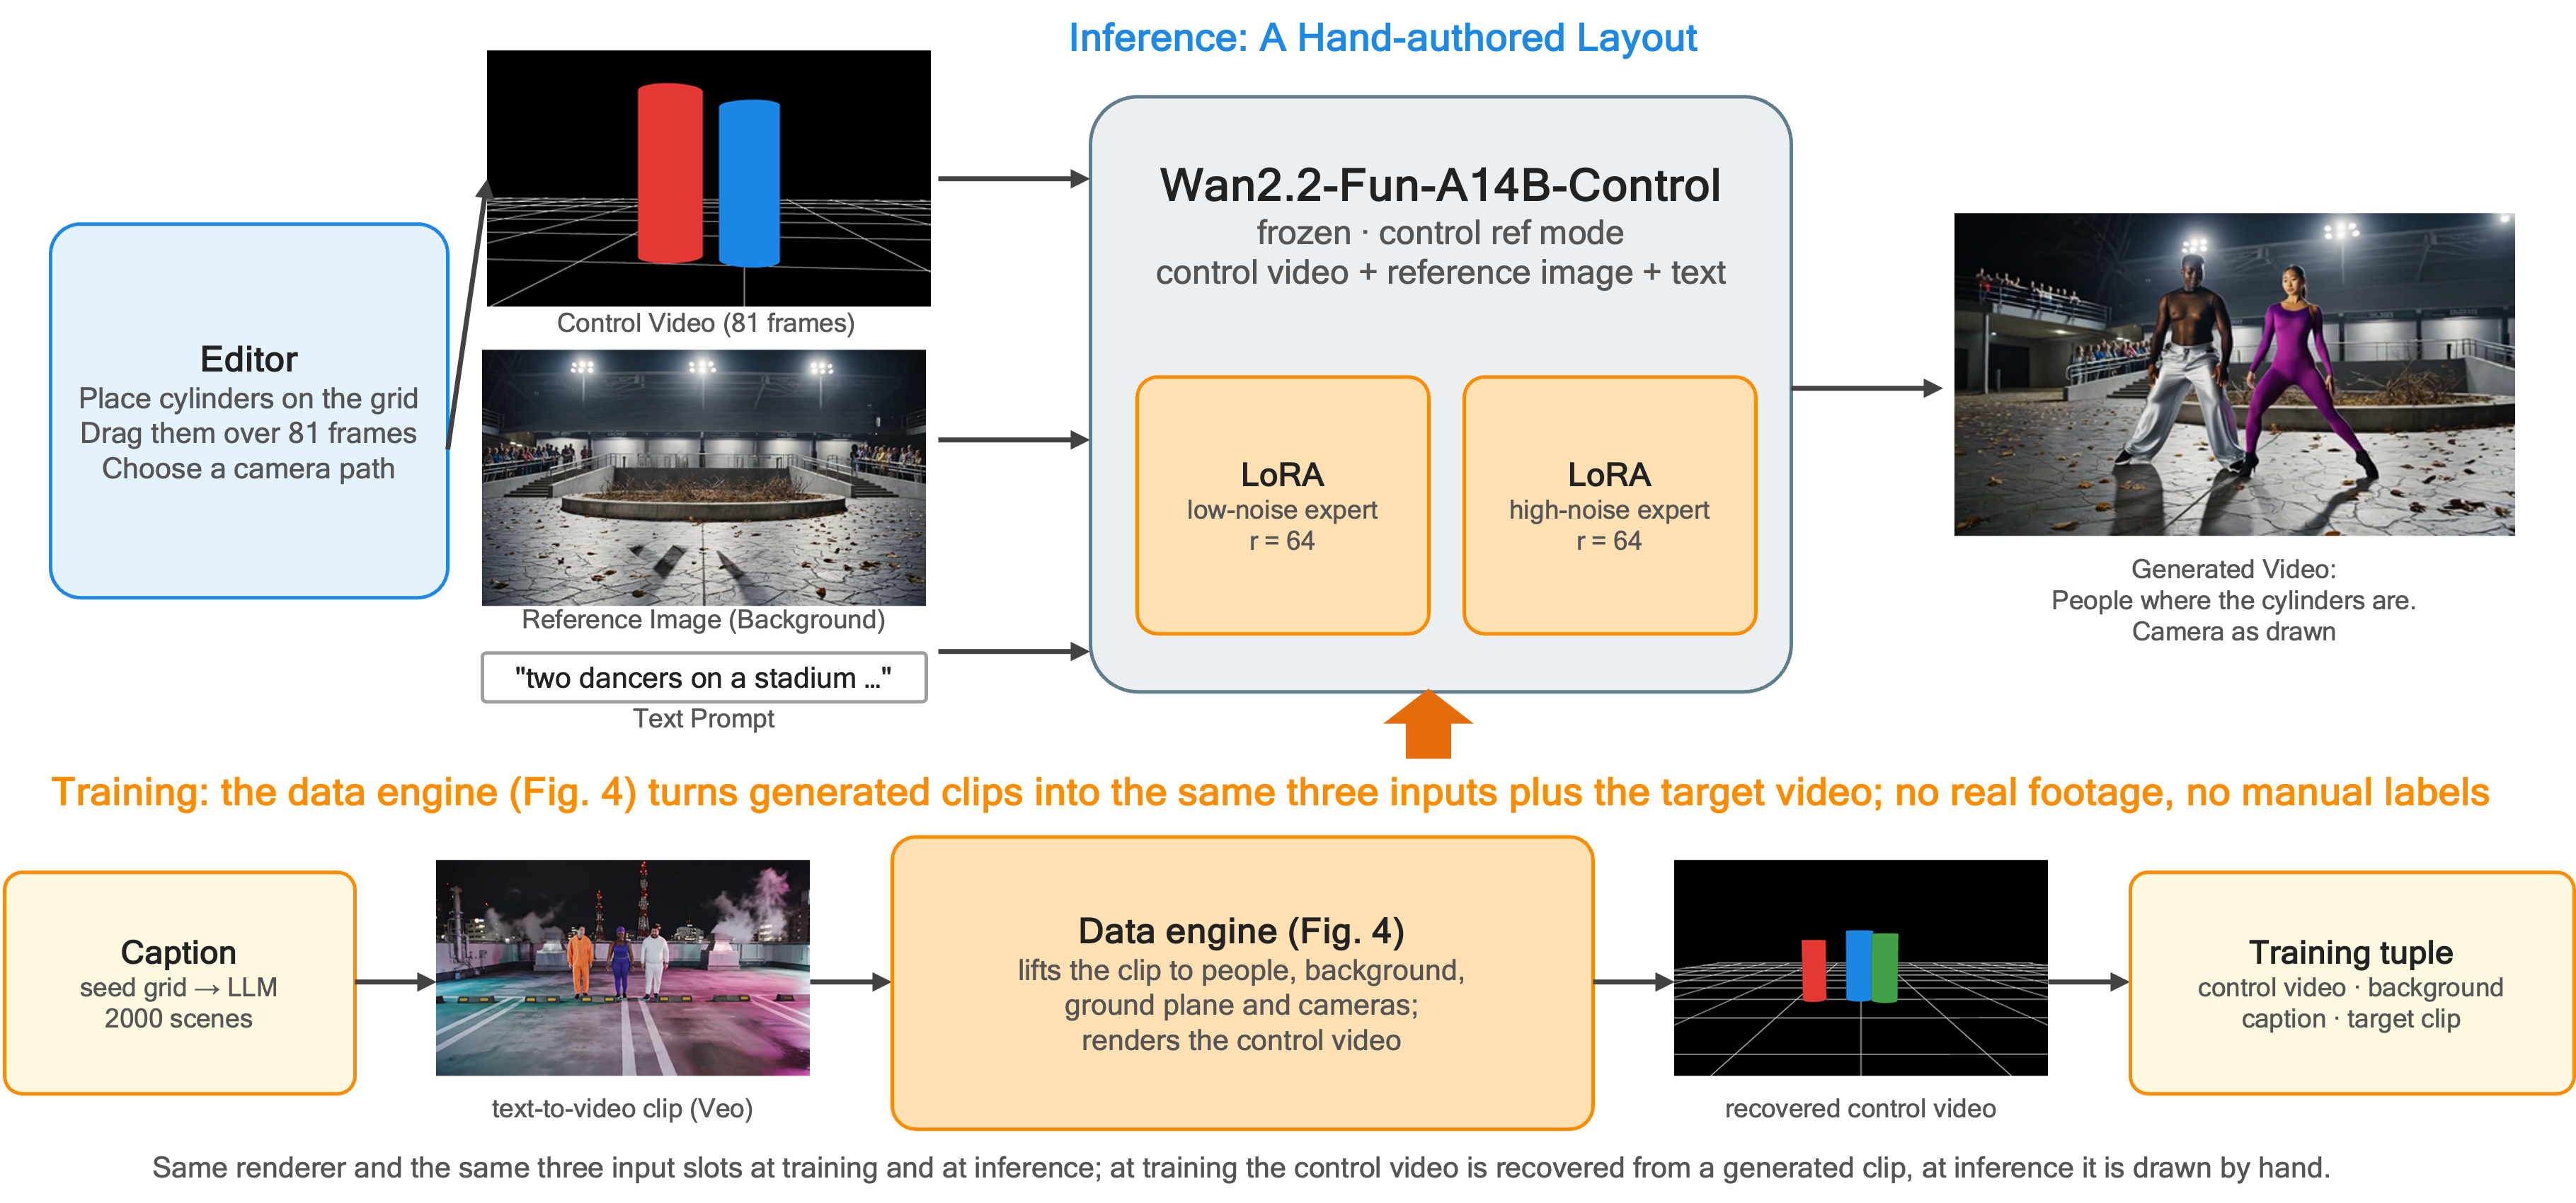
Top: inference from a hand-authored layout (editor → control video + reference image + text → Wan2.2-Fun-Control with one LoRA per expert). Bottom: training tuples come from the data engine; the renderer and the three input slots are the same in both.
How the training pairs are made
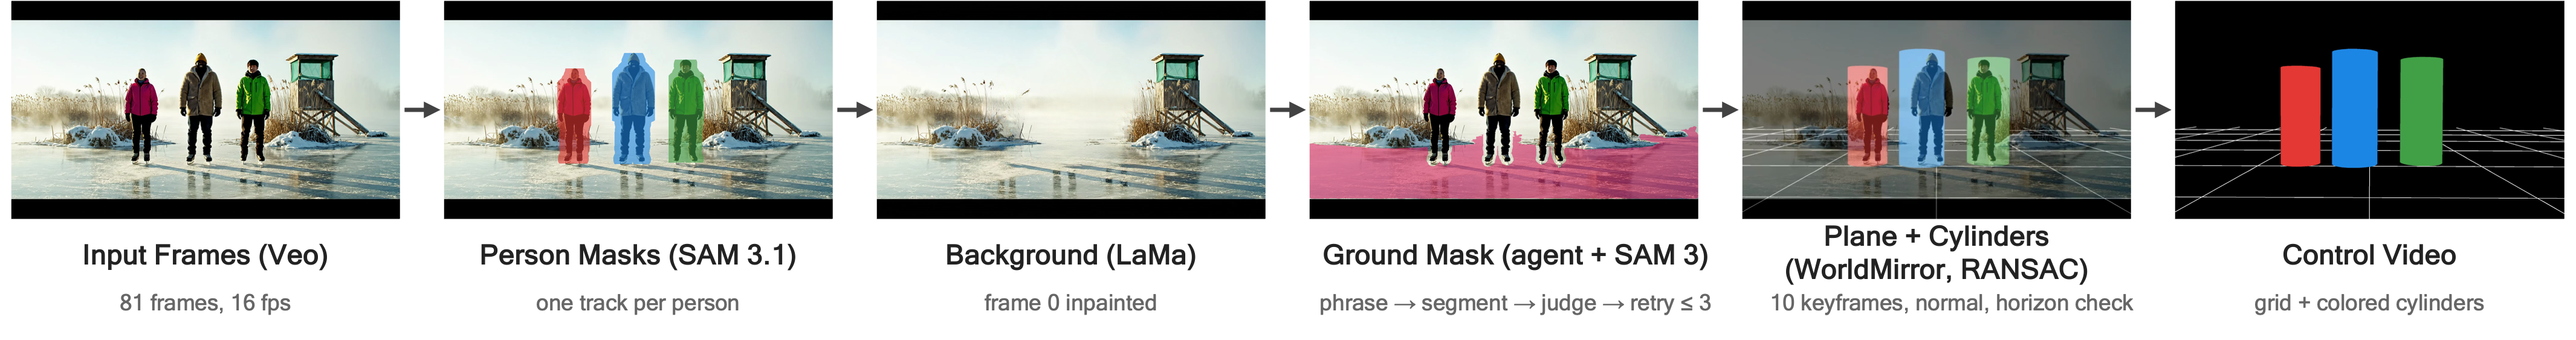
One clip through the data engine: input frame, person masks (SAM 3.1), background (LaMa), ground mask (agent loop over SAM 3 phrases), plane and cylinders (HunyuanWorld-Mirror cameras and points, RANSAC plane), control frame.
Baselines on hold-out clips
Own caption, own background, the control video recovered from the clip; the original Veo clip for reference.
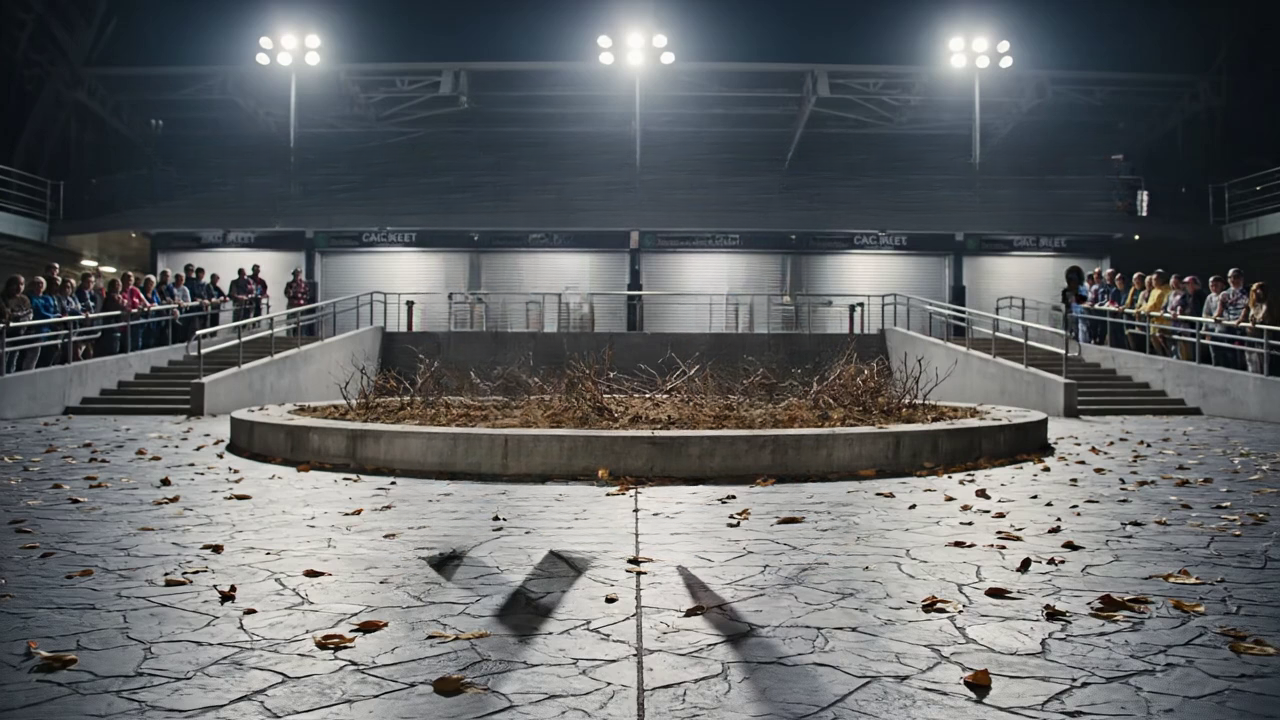
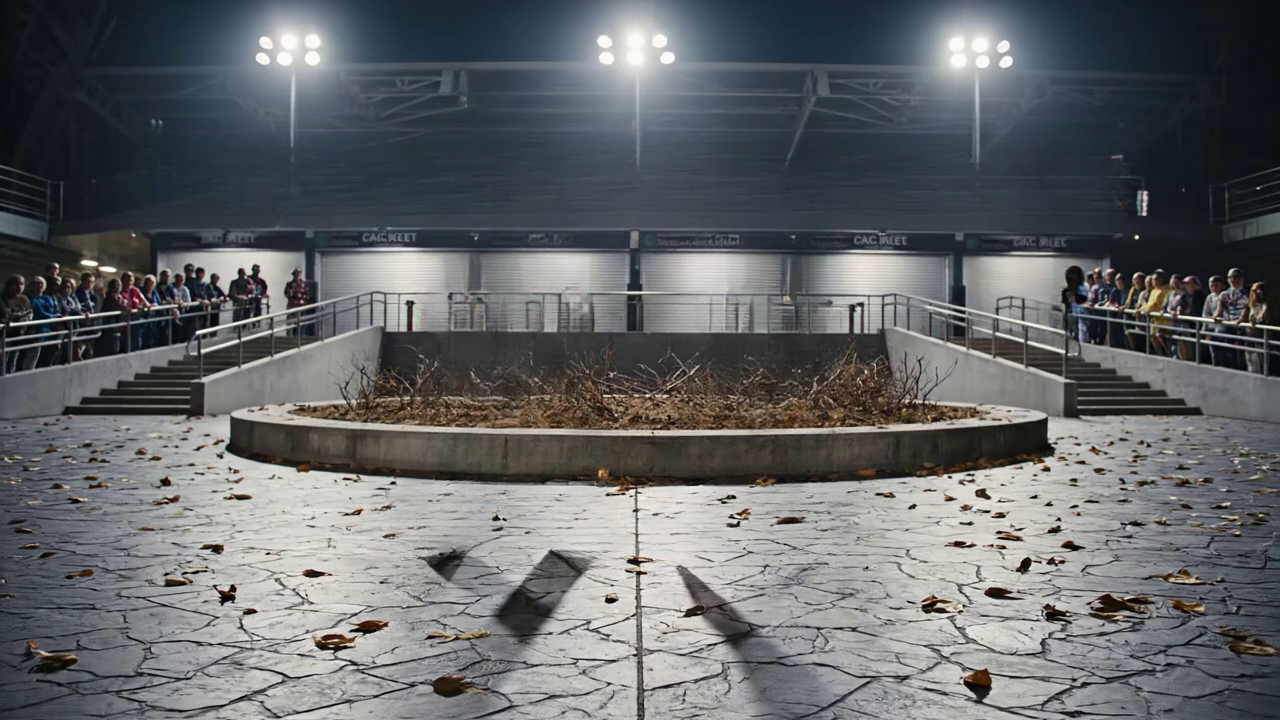
c0599: two dancers on a stadium plaza.
c0899: three skaters on a frozen lagoon (bar-free reference; the Veo clip was letterboxed).
Change the people (text only)
Same control video and background as the baseline.
c0599: elderly Scottish man in tweed + young Nigerian woman in a yellow raincoat.
c0899: Norwegian man in a red sweater, Korean woman in a black puffer and white helmet, Mexican man in a blue tracksuit.
Change the background (reference image)
Same control video; the reference image and the scene words swapped between the two clips.
c0599 dancers on the frozen lagoon.
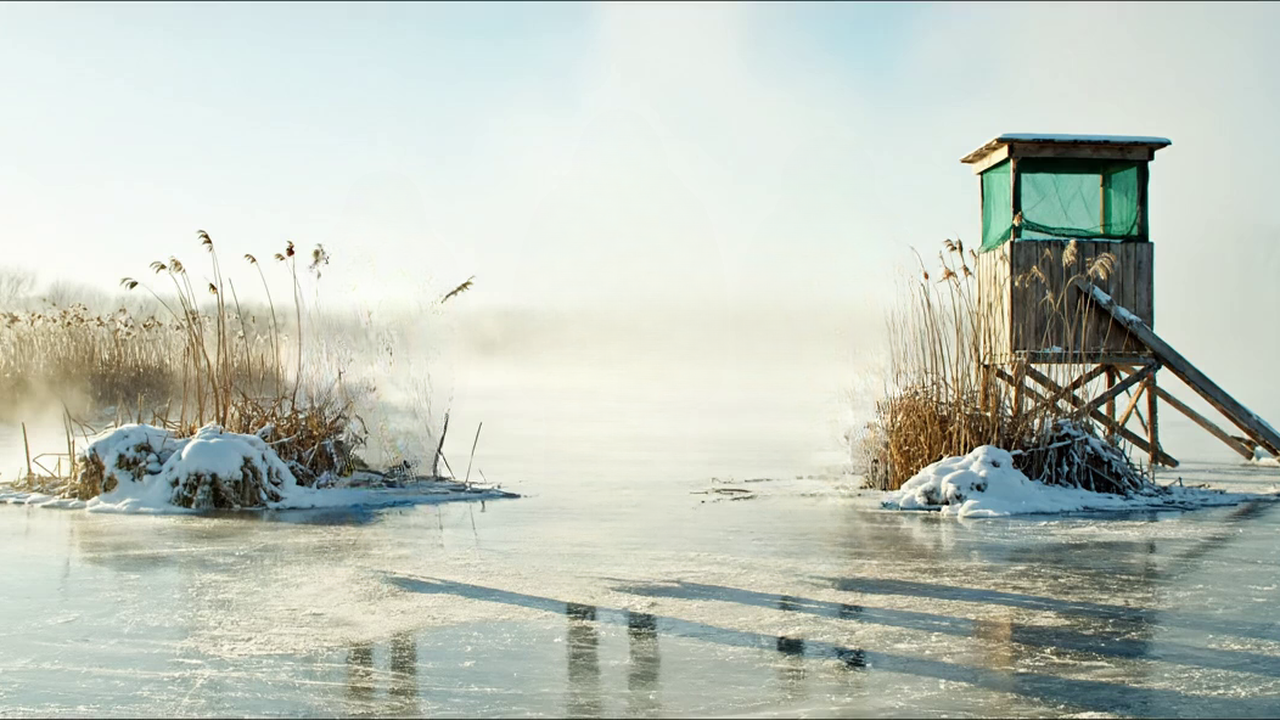
c0899 skaters on the stadium plaza.
Change the camera (authored paths on the recovered geometry)
Same cylinders, caption and reference image; the camera path re-rendered.
c0599: static.
c0599: dolly in.
c0599: dolly out.
c0599: orbit.
c0599: pan.
c0599: crane.
c0899: orbit.
c0899: dolly in.
Unseen scenes: the background reference image comes from a different hold-out clip
Geometry of one hold-out clip, background of another; the model saw neither.
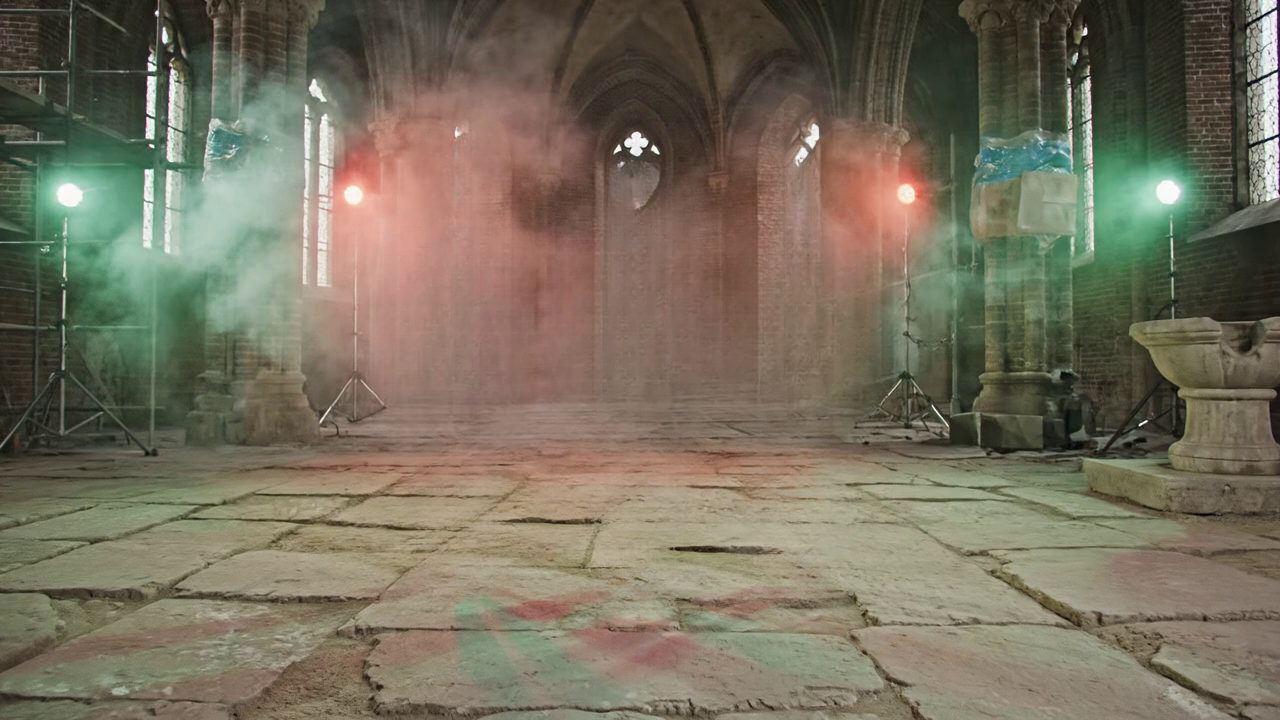
Two dancers (c0599 geometry) in a deconsecrated cathedral (reference of c0249).
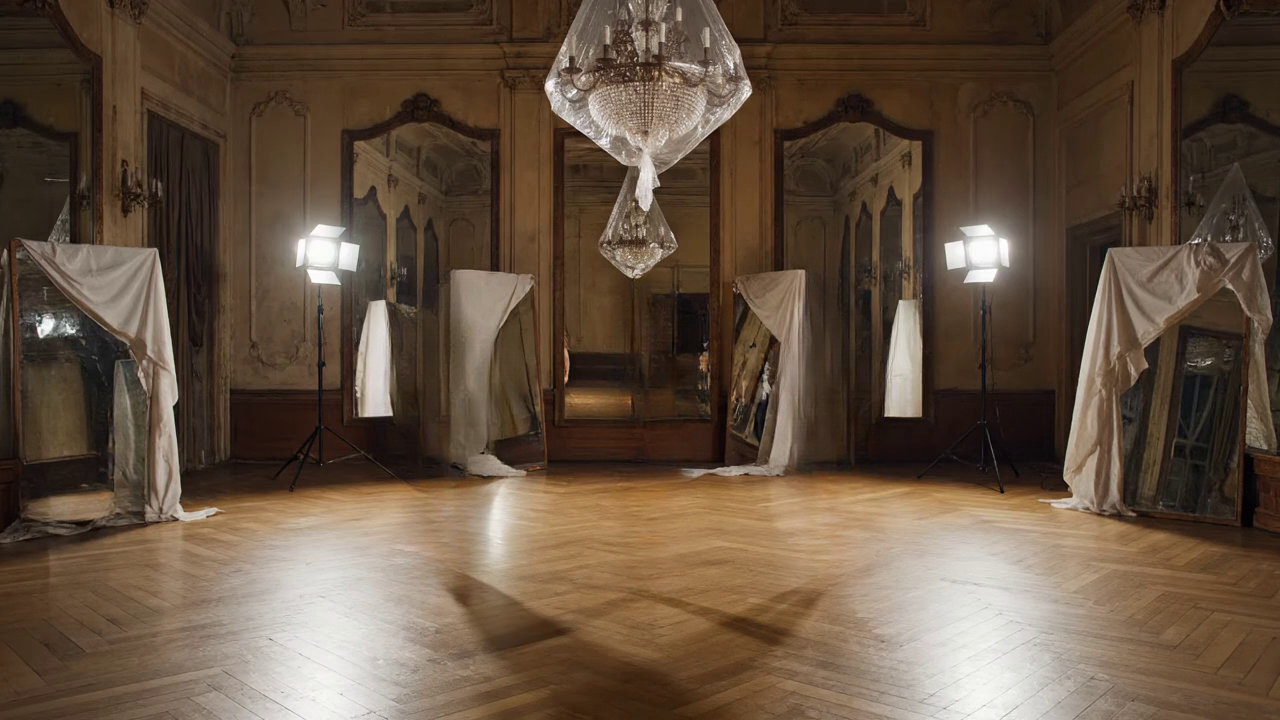
Two dancers in a faded Moscow ballroom (reference of c1699).
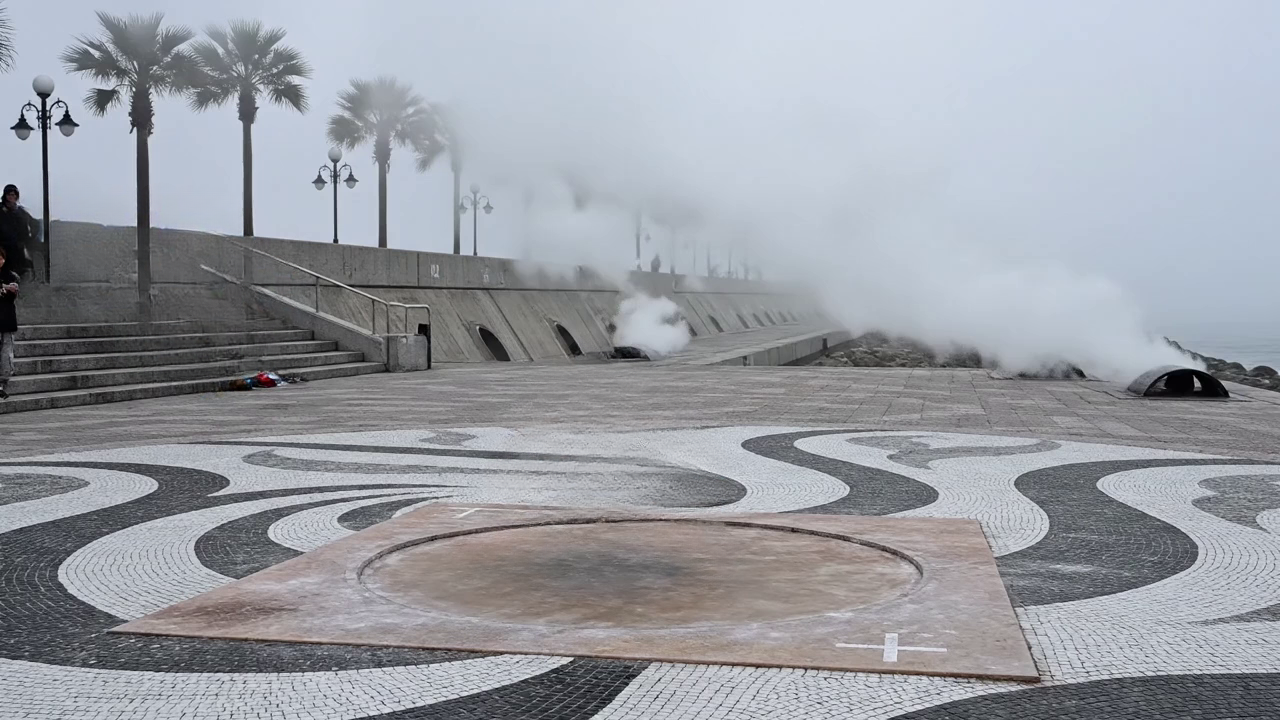
Three skaters (c0899 geometry) on a foggy Tokyo promenade (reference of c1549).
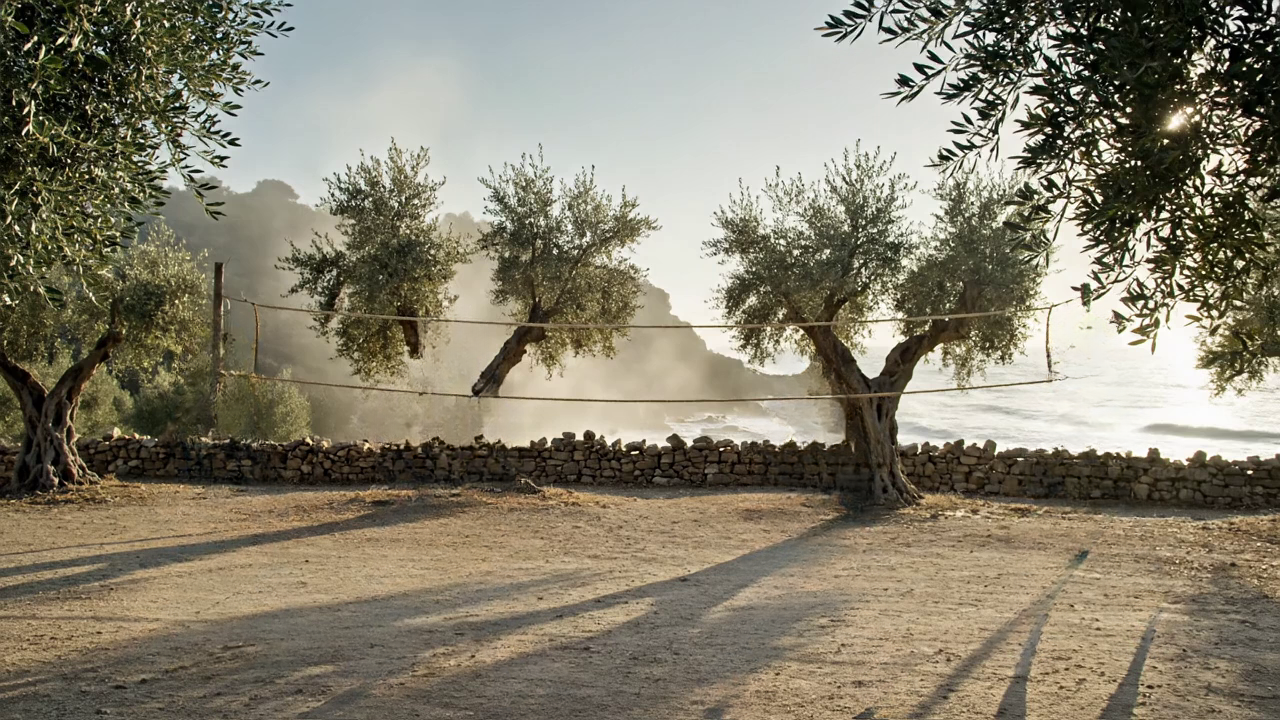
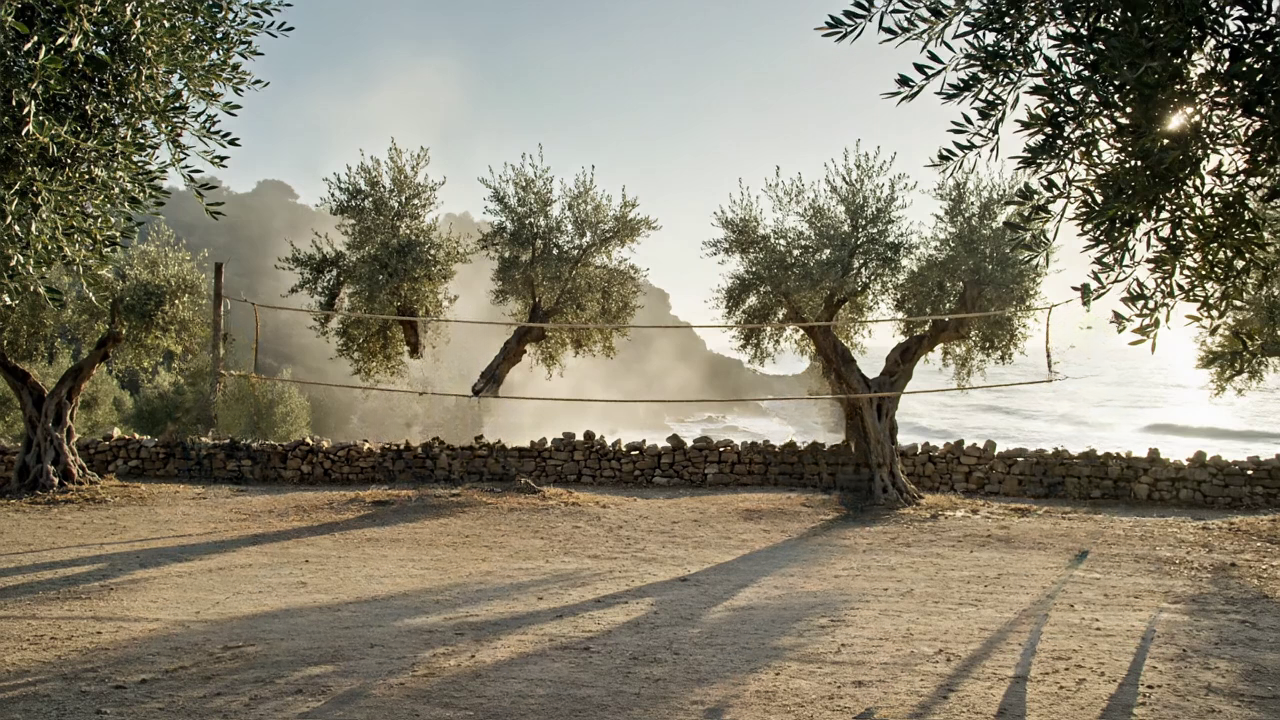
Three people on an olive grove terrace (reference of c0999).
Unseen actions: prompts outside the 118 training action families
Same geometry and background as the baselines, only the action in the text changed.
Slow tai chi in unison.
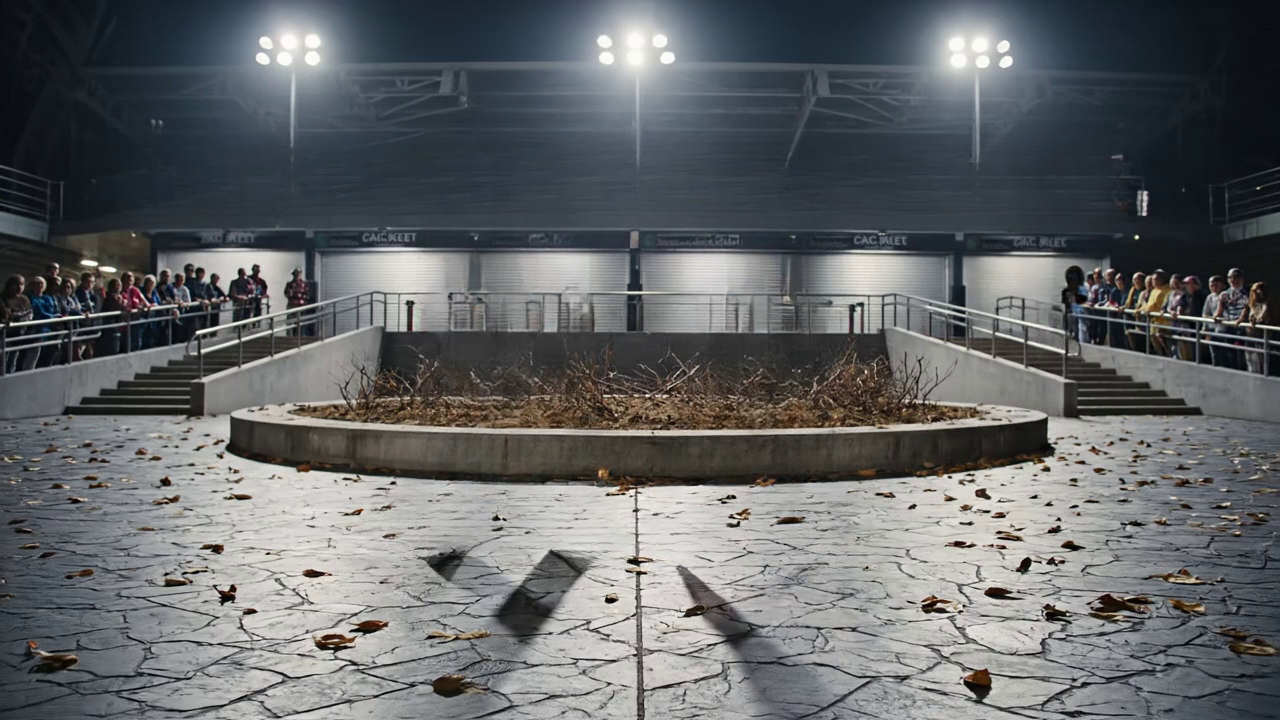
Juggling three balls each.
Walking briskly and chatting.
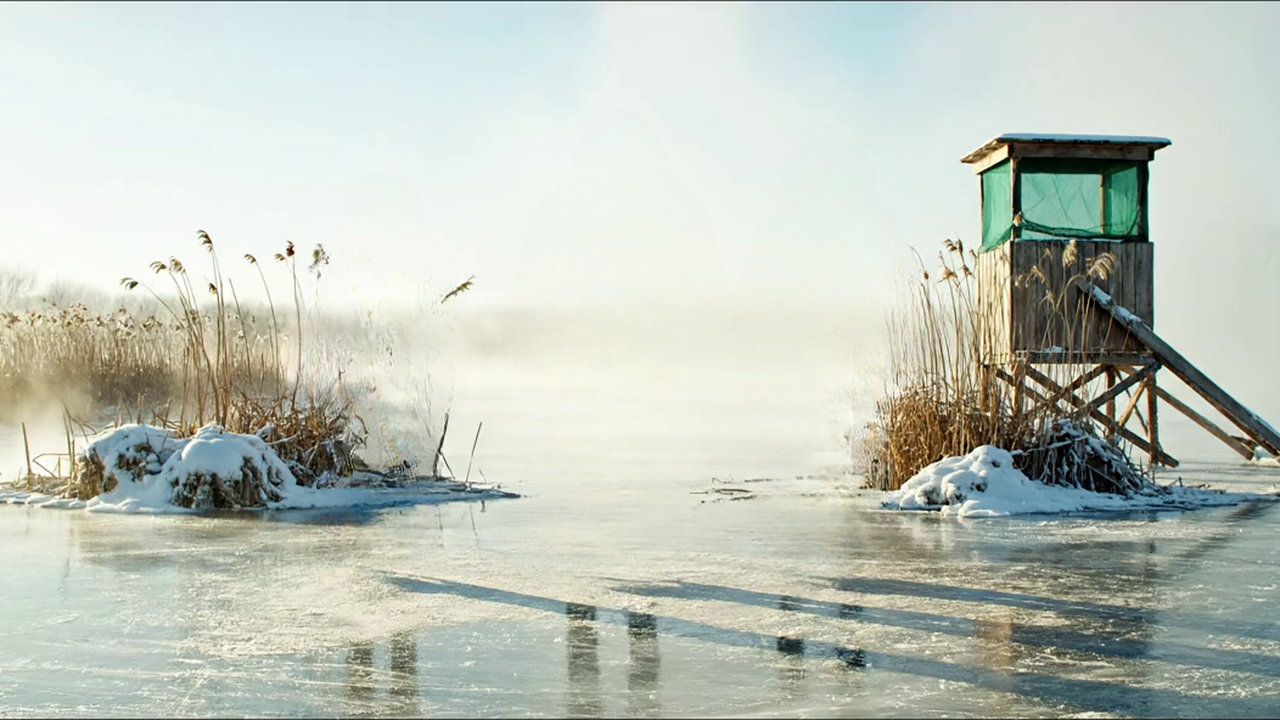
Carrying a long ladder together.
Hand-authored geometry, never seen in training (work in progress)
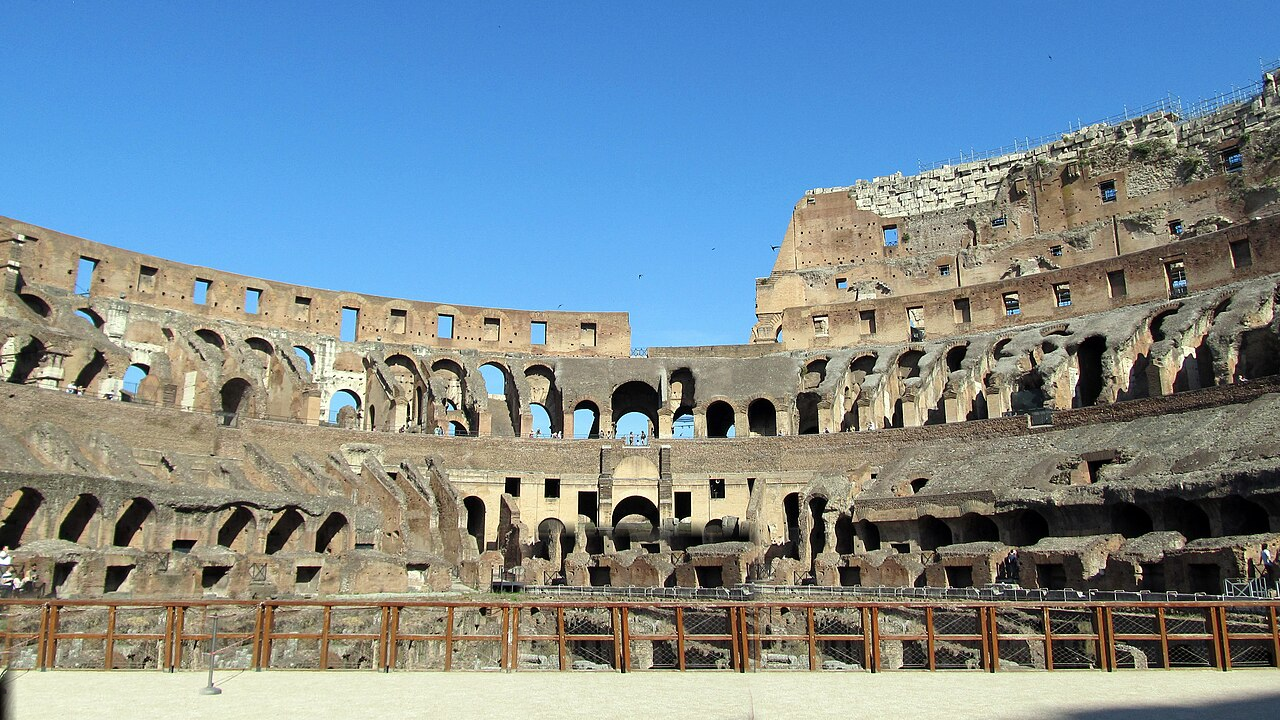
Control videos drawn in the editor and rendered with the same renderer as the training data. With a photograph as background the camera must first be fitted to the photo (GeoCalib); without the fit the scale is wrong. Several cases below still show problems and are labelled as such.
Two Roman soldiers fight in the Colosseum (background: a Wikimedia Commons photo, CC BY-SA 2.0 daryl_mitchell, tourists patched out). Camera fitted to the photograph with GeoCalib (focal length + horizon), static.
Fitted camera, orbit anchored to the photo pose. Partial: first frame at the right scale, the fighters grow towards the end.
Fitted camera, dolly in.
Fitted camera, pan (failure: a helmet fills the left of the first frames).
Same duel WITHOUT fitting the ground (default authoring camera). Failure: the fighters come out far larger than the cylinders prescribe. Static.
Default camera, orbit. Failure: wrong scale (too large, too close).
Default camera, dolly in. Failures: the fighters do not swap sides as the cylinders do, and the scale is wrong.
Default camera, crane (not followed: the video stays at the photo viewpoint).
Two people swap places along curved paths under an orbiting camera (stadium plaza background of hold-out c0599).
Four people of different heights in a row, dolly in (olive grove background of hold-out c0999).
Stress tests: cases chosen to break the model
Hand-authored geometry on the plaza background; each pushes one factor outside the training range (count, occlusion, camera, viewpoint, height ratio, or a prompt that contradicts the geometry).
Six people in a diagonal line (the training maximum).
Eight people (beyond the training range; colours cycle).
Two people crossing paths twice (occlusion).
Orbit of 90 degrees (training: +-20).
Dolly in over 2.4 subject heights (training: at most 1.2).
Camera 3 subject heights up, pitched 55 degrees down.
Camera 0.2 subject heights above the ground, level.
A 1.7-unit adult next to a 0.6-unit child.
Three cylinders, but the prompt says one woman alone.
Standing cylinders, but the prompt says two people sit on the ground.
One person walks from far away past the camera.
No cylinders at all; the prompt asks for an empty plaza.
All videos: 480 x 832, 81 frames at 16 fps, 50 sampling steps, LoRA weight 0.55 on both experts, one fixed seed, no cherry-picking within a case. Videos loop; hover to see the controls.
Data and weights
LoRA weights (both experts): Hugging Face, link above. Captions and seed cards: in the code repository. Training set (81-frame clips, control videos, background images, metadata): Google Drive folder (CoaG_train_data.tar, 9.8 GB; raw Veo clips to follow). Colosseum background: "Colosseum Interior 1" by daryl_mitchell, CC BY-SA 2.0, via Wikimedia Commons (cropped, tourists patched out).